Generalized Least Squares and Clustered Dependence
Lecture 7
0.1 Where we are
Where this lecture sits
DGPIdentificationEstimationAsymptoticsInference
Computation
Lectures 4–5 already made heteroskedasticity the default: \(\E[\beps\beps'\mid\bX]=\bD\) is a general positive-definite matrix, OLS is consistent, and the robust (sandwich) standard errors deliver valid inference with no homoskedasticity assumption. So the classical “violation of A4” story is behind us. Two questions remain — and they are what this lecture is about.
The reordering of the course did the heavy lifting here. What used to be “the heteroskedasticity lecture” — deriving the sandwich variance, White’s estimator, showing that \(s^2(\bX'\bX)^{-1}\) is wrong — now lives in Lectures 4 and 5, as the general case. Building on that, this lecture asks the two things robust OLS does not settle: whether we can estimate \(\bbeta\) more efficiently, and what to do when errors are correlated across observations.
Two questions robust OLS does not answer
The two questions have very different answers. Efficiency leads to generalized least squares — a better estimator if we know (or can model) \(\bD\), but one that trades robustness for that efficiency. Dependence leads to cluster-robust inference — not a better estimator at all, but a different variance, because the design of the sample changed.
1 Part I · The generalized model and the cost to OLS
1.1 The generalized regression model
One assumption, dropped long ago
The model is the familiar linear one, with the error covariance left general: \[\bY=\bX\bbeta+\beps,\qquad \E[\beps\mid\bX]=\bzero,\qquad \E[\beps\beps'\mid\bX]=\bD,\] with \(\bD\) symmetric positive-definite (an \(n\times n\) matrix). Homoskedasticity, \(\bD=\sigma^2\bI\), is the special case — not the starting point.
Definition 1 (The two leading structures) Heteroskedasticity (this lecture’s focus): errors uncorrelated across observations but with different variances — \(\bD=\operatorname{diag}(\sigma_1^2,\dots,\sigma_n^2)\), i.e. \(\E[\varepsilon_i^2\mid\mathbf{x}_i]=\sigma_i^2(\mathbf{x}_i)\). Dependence: \(\bD\) has non-zero off-diagonal entries — serial correlation (time series) or within-cluster correlation (Part V).
OLS still works — it just is not the best
Nothing about consistency or valid inference breaks under a general \(\bD\):
This is the exact sense in which the lecture is about efficiency, not validity. OLS gives you the right answer with honest uncertainty. The open question is whether another linear unbiased estimator has a smaller variance — and Lecture 5’s “asymptotic efficiency” slide already told us where to look: the estimator that attains the efficiency bound is generalized least squares.
2 Part II · Generalized Least Squares
2.1 The cost of ignoring D
Every observation weighted equally
A general \(\bD\) can break A4 in two ways — heteroskedasticity (the diagonal of \(\bD\) varies across observations) or autocorrelation (non-zero off-diagonals), or both. OLS stays unbiased and consistent either way, but it pays for ignoring \(\bD\) in precision. Compare the variance OLS assumes with the true one: \[\underbrace{\sigma^2(\bX'\bX)^{-1}}_{\text{under A4}} \qquad\text{vs.}\qquad \underbrace{(\bX'\bX)^{-1}\bX'\bD\bX(\bX'\bX)^{-1}}_{\text{true, general }\bD}.\]
Following Greene: the conventional variance is built from \(\sum_i\mathbf{x}_i\mathbf{x}_i'\) — weight \(1\) on every \(\mathbf{x}_i\mathbf{x}_i'\) — whereas the true variance weights the \(i\)-th term by \(\sigma_i^2\) (through \(\bX'\bD\bX\)). The two agree only when all \(\sigma_i^2\) are equal, i.e. A4. Otherwise OLS spreads its attention equally over observations that deserve unequal trust, and a re-weighted estimator must do better. That estimator is GLS; the weight that “should” appear, \(1/\sigma_i^2\), emerges on its own.
2.2 GLS with known D
Transforming to constant variance
If the trouble is unequal (and correlated) variances, the cure is to rescale the observations so the variances become equal and the correlations vanish — then the classical model, and OLS’s optimality, are back. Since \(\bD\) is positive-definite, there is a matrix \(\mathbf{L}\) with \[\mathbf{L}\,\bD\,\mathbf{L}'=\bI,\qquad\text{equivalently}\qquad \bD^{-1}=\mathbf{L}'\mathbf{L}\] — the matrix analogue of “dividing by the standard deviation” (a Cholesky factor is one such \(\mathbf{L}\)).
On the Board
Pre-multiply the model by \(\mathbf{L}\): with \(\bY_*=\mathbf{L}\bY\), \(\bX_*=\mathbf{L}\bX\), \(\beps_*=\mathbf{L}\beps\), \[\bY_*=\bX_*\bbeta+\beps_*,\qquad \E[\beps_*\beps_*'\mid\bX]=\mathbf{L}\,\bD\,\mathbf{L}'=\bI.\] The transformed errors are homoskedastic and uncorrelated — the classical model holds for \((\bY_*,\bX_*)\), so OLS on the transformed data is efficient. That is GLS.
The GLS estimator
Theorem 1 (Generalized least squares) OLS on the transformed model is \[\hat{\bbeta}_{\text{GLS}} =(\bX_*'\bX_*)^{-1}\bX_*'\bY_* =(\bX'\bD^{-1}\bX)^{-1}\bX'\bD^{-1}\bY.\] Among linear unbiased estimators it has the smallest variance — the generalized Gauss–Markov (Aitken) theorem — with \[\Var[\hat{\bbeta}_{\text{GLS}}\mid\bX]=(\bX'\bD^{-1}\bX)^{-1}.\] OLS is the special case \(\bD=\sigma^2\bI\) (weight matrix \(\bI\) instead of \(\bD^{-1}\)).
GLS re-weights: it downweights high-variance observations and upweights precise ones, which is exactly the information OLS ignores by treating every observation alike. The efficiency gain is the payoff Lecture 5 promised — \(\Var[\hat{\bbeta}_{\text{GLS}}]\preceq\Var[\bb]\) in the psd order, whenever \(\bD\neq\sigma^2\bI\). Under i.i.d. sampling the result is stronger still (Hansen’s modern Gauss–Markov): \((\bX'\bD^{-1}\bX)^{-1}\) is the smallest variance among all unbiased estimators — not only linear ones — a semiparametric efficiency bound.
Weighted least squares: the heteroskedastic case
Corollary 1 (Weighted least squares) When the violation is pure heteroskedasticity, \(\bD=\operatorname{diag}(\sigma_1^2,\dots,\sigma_n^2)\), the transformation is just dividing each observation by its own \(\sigma_i\) (\(\mathbf{L}=\operatorname{diag}(1/\sigma_1,\dots,1/\sigma_n)\)). GLS then takes the familiar weighted form \[\hat{\bbeta}_{\text{WLS}} =\Big(\textstyle\sum_i \tfrac{1}{\sigma_i^2}\,\mathbf{x}_i\mathbf{x}_i'\Big)^{-1}\Big(\textstyle\sum_i \tfrac{1}{\sigma_i^2}\,\mathbf{x}_i y_i\Big) \ -\ \text{exactly the weighting OLS was missing.}\]
3 Part III · Feasible GLS
3.1 When D is unknown
The skedastic regression
GLS needs \(\bD\), which we never know. But an unrestricted \(\bD\) has \(n\) variances — too many to estimate from \(n\) observations. Model the variance with a few parameters:
Definition 2 (The skedastic regression) Specify \(\sigma_i^2=\sigma^2(\mathbf{z}_i,\boldsymbol{\alpha})\) for a small parameter vector \(\boldsymbol{\alpha}\) and observed \(\mathbf{z}_i\) (often a subset/transform of \(\mathbf{x}_i\)) — for example the linear \(\sigma_i^2=\alpha_0+\mathbf{z}_i'\boldsymbol{\alpha}_1\) or the multiplicative \(\sigma_i^2=\exp(\alpha_0+\mathbf{z}_i'\boldsymbol{\alpha}_1)\). Estimate \(\boldsymbol{\alpha}\) by regressing the squared OLS residuals \(\hat e_i^2\) on \(\mathbf{z}_i\) — the skedastic regression.
The squared residual \(\hat e_i^2\) is a noisy but consistent proxy for \(\sigma_i^2\) (OLS is consistent, so \(\hat e_i\) tracks \(\varepsilon_i\)). Regressing \(\hat e_i^2\) on \(\mathbf{z}_i\) recovers how the variance moves with \(\mathbf{z}_i\). Replacing the true \(\sigma_i^2\) by the fitted \(\hat\sigma_i^2\) is what makes GLS feasible.
The FGLS estimator
Theorem 2 (Feasible GLS) Form \(\widehat{\bD}=\operatorname{diag}(\hat\sigma_1^2,\dots,\hat\sigma_n^2)\) from the skedastic regression and plug it in: \[\hat{\bbeta}_{\text{FGLS}}=(\bX'\widehat{\bD}^{-1}\bX)^{-1}\bX'\widehat{\bD}^{-1}\bY.\] If the skedastic model is correctly specified, estimating \(\boldsymbol{\alpha}\) is asymptotically free: \(\hat{\bbeta}_{\text{FGLS}}\) has the same asymptotic distribution as infeasible GLS.
On the Board
Why “asymptotically free”: the sampling error in \(\hat{\boldsymbol{\alpha}}\) enters \(\hat{\bbeta}_{\text{FGLS}}\) only through \(\widehat{\bD}\pto\bD\), and a \(\sqrt{n}\)-consistent \(\hat{\boldsymbol{\alpha}}\) perturbs \(\hat{\bbeta}\) by a term that vanishes faster than \(1/\sqrt{n}\). So FGLS and GLS share the limit \(\Normal(\bzero,(\bX'\bD^{-1}\bX/n)^{-1})\).
3.2 Why not always FGLS?
The efficiency–robustness trade-off
If FGLS is efficient and asymptotically free, why is OLS still the default? Three reasons — this is the heart of the lecture.
OLS is a robust estimator. The deepest reason is the third. If the equation is a projection (a best linear approximation) rather than a true CEF, OLS still estimates that projection consistently — but weighting by \(\widehat{\bD}^{-1}\) changes the target, so FGLS estimates something else. Efficiency and robustness pull in opposite directions: FGLS buys a smaller variance by betting the conditional mean is exactly right. The standard advice is OLS with robust (or cluster-robust) standard errors — the safe default — with FGLS reserved for cases where the variance structure is genuinely known.
This resolves the guiding question. Robust inference already handles heteroskedasticity for validity; FGLS offers efficiency, but conditionally and at a real cost. So the practical hierarchy is: OLS + robust by default; WLS/FGLS when you have a credible, verified model for \(\bD\) (e.g. known grouping, survey weights, a physical variance law).
4 Part IV · Testing for heteroskedasticity
4.1 The skedastic regression, tested
White and Breusch–Pagan are one test
Theorem 3 (Testing constant variance) Homoskedasticity is \(H_0:\boldsymbol{\alpha}_1=\bzero\) in the skedastic regression \(\hat e_i^2=\alpha_0+\mathbf{z}_i'\boldsymbol{\alpha}_1+\nu_i\) — the variance does not depend on \(\mathbf{z}_i\). Test it with the joint Wald/\(F\) on \(\boldsymbol{\alpha}_1\) (equivalently \(nR^2\dto\chi^2_q\), \(q=\dim\boldsymbol{\alpha}_1\)). The two classic choices differ only in \(\mathbf{z}_i\): White uses the squares and cross-products of \(\mathbf{x}_i\); Breusch–Pagan uses a general \(\mathbf{z}_i\). Under independence they are essentially the same test.
Both read off a single auxiliary regression of squared residuals. White’s choice of \(\mathbf{z}_i\) makes the test omnibus (it also picks up misspecification); Breusch–Pagan targets a direction you specify. The statistic is the joint significance of that regression — nothing new relative to Part II of Lecture 6.
What the test is — and is not — for
Under the Hood—Do not misuse the test
A heteroskedasticity test answers one scientific question: does \(\sigma^2\) depend on the regressors? It is not a tool to choose between OLS and FGLS, nor between classical and robust standard errors — “hypothesis tests are not designed for these purposes.” You use robust errors regardless of the test. Run the test only if whether \(\sigma^2(\mathbf{x})\) varies is itself of economic interest.
5 Part V · Clustered dependence
5.1 When observations come in groups
Clusters: dependence by design
Definition 3 (Clustered sampling) The sample is \(C\) groups (clusters) — firms in industries, students in schools, individuals in villages — \[y_{i,c}=\mathbf{x}_{i,c}'\bbeta+\varepsilon_{i,c},\] with errors correlated within a cluster but independent across clusters — off-diagonal structure in \(\bD\), block by block, from how the sample was drawn. OLS stays unbiased when \(\E[\beps_c\mid\bX_c]=\bzero\), which requires within-cluster interactions to be in the model (a pupil’s outcome must not depend on classmates’ regressors).
How bad can it get? With equal clusters of size \(N\), intra-cluster correlation \(\rho\), and a cluster-constant regressor, the design effect (Moulton) inflates the variance by \(1+\rho(N-1)\): at \(\rho=0.25,\ N=48\) the correct standard error is about three times the conventional one. Ignoring clustering does not nudge the errors — it can shrink them several-fold.
The cluster-robust variance
Theorem 4 (Cluster-robust covariance) With \(\bX_c,\beps_c\) the regressors and errors of cluster \(c\), OLS is unchanged, and \[\Var[\bb\mid\bX]=(\bX'\bX)^{-1}\Big[\textstyle\sum_{c=1}^{C}\bX_c'\,\bD_c\,\bX_c\Big](\bX'\bX)^{-1}, \qquad \bD_c=\E[\beps_c\beps_c'\mid\bX_c].\] It is estimated by the cluster sandwich, summing the cluster score vectors \(\bX_c'\hat{\be}_c\): \[\widehat{\Asyvar}[\bb]=(\bX'\bX)^{-1}\Big[\textstyle\sum_{c=1}^{C}(\bX_c'\hat{\be}_c)(\bX_c'\hat{\be}_c)'\Big](\bX'\bX)^{-1}.\] White’s estimator is the special case of one observation per cluster (\(\bD_c\) scalar).
The construction mirrors White’s exactly, but the “meat” now sums outer products of cluster totals \(\bX_c'\hat{\be}_c\) instead of individual \(\hat e_i^2\mathbf{x}_i\mathbf{x}_i'\) — that is what captures the within-cluster covariances. Everything else — the bread \((\bX'\bX)^{-1}\), the sandwich shape — is identical.
The catch: asymptotics in the number of clusters
Under the Hood—Few clusters break the sandwich
The cluster-robust variance is consistent as the number of clusters \(C\to\infty\) — not as \(n\to\infty\). Stata’s finite-sample correction multiplies it by \(a_n=\dfrac{n-1}{n-k}\cdot\dfrac{C}{C-1}\) (the \(C/(C-1)\) helps when \(C\) is small; \(C=n\) recovers the i.i.d. factor). But no correction rescues small \(C\): \(C\) is the effective sample size — \(C=50\) clusters is like heteroskedasticity-robust inference with \(n=50\) observations, and unequal cluster sizes make it worse. Treat it as a small-sample problem, not a fixed reference distribution.
The reliable finite-sample tools are resampling, in Lecture 8. The wild cluster bootstrap multiplies each cluster’s residual vector by a single \(\pm1\) (Rademacher) weight — one draw per cluster, preserving within-cluster dependence — then re-computes the statistic (the restricted version, under \(H_0\), is recommended). The delete-cluster jackknife drops one whole cluster at a time; both are formula-free alternatives to the sandwich.
5.2 At what level to cluster?
The cluster level is a choice
The cluster level is a choice, and it is a genuine trade-off — not “always cluster more”.
5.3 When robust is not enough
The limits of a robust variance
The Four Questions—What robust standard errors do and do not fix
- They fix the variance — the sandwich (White or cluster) gives valid standard errors under heteroskedasticity or clustering.
- They do not fix inconsistency — if \(\E[\mathbf{x}\varepsilon]\neq\bzero\) (endogeneity, Lecture 10), no variance formula saves you; the point estimate is wrong.
- They do not fix dependence you failed to model — the White errors are wrong under clustering; you must match the sandwich to the actual dependence structure.
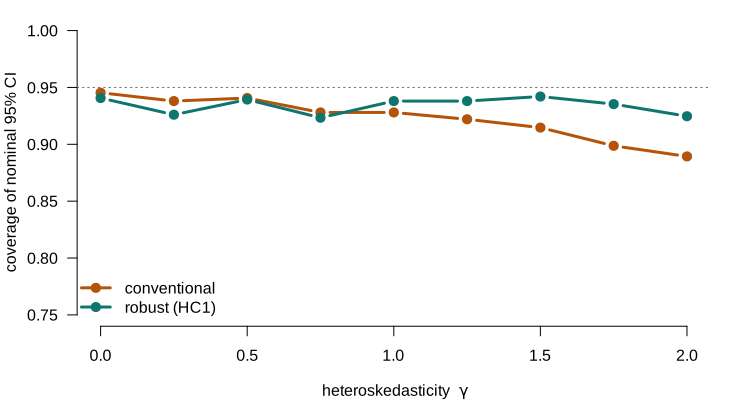
5.4 Seeing it: coverage under heteroskedasticity
Does the interval cover 95%?